What should an agent trace tell the operator?
AI agent observability should let an operator reconstruct one business task: which version ran, what data and tools it used, where it waited or failed, what it cost, and whether the intended action actually completed. Start with a trace that connects those events, then add metrics and alerts that lead to a named response. A successful model call or a low average response time does not establish a correct business outcome.
This guide is for a team operating an agent that reads business data or calls tools. The parent AI automation guide covers the wider rollout. Here, the task is to design the evidence and response path after release, rather than choose the agent’s authority or build its pre-release test suite.
Which events belong in one trace?
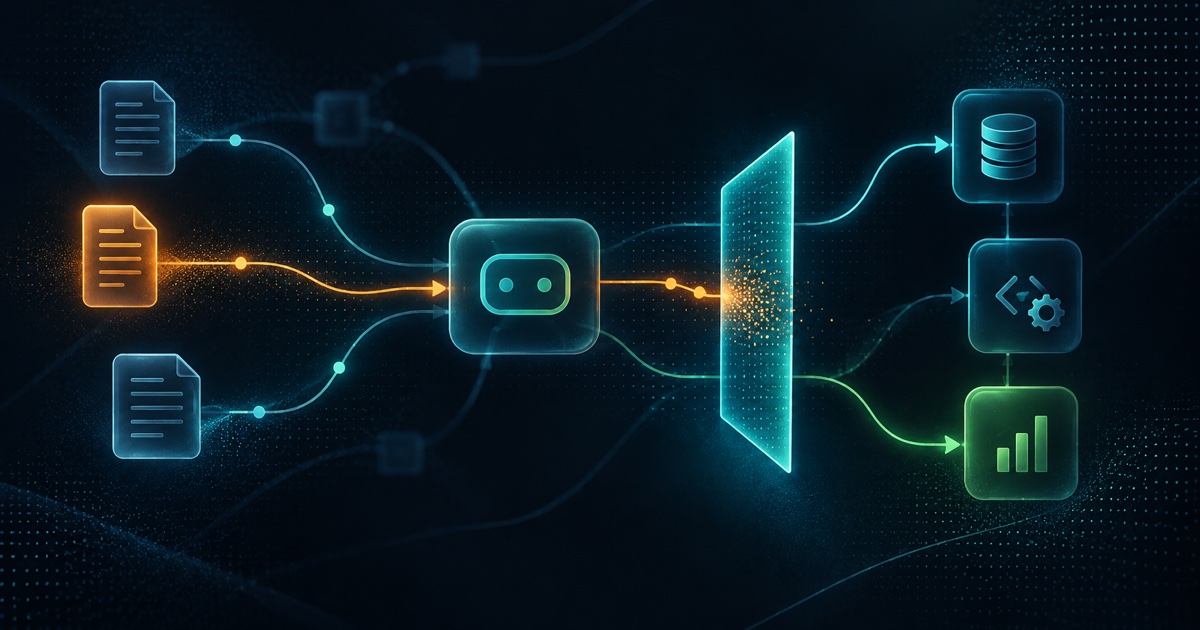
A trace connects the steps of a request; a span records one operation inside that trace. Langfuse’s tracing documentation describes recording model calls, retrieval, tools, timing, and metadata as connected operations. For a business workflow, extend that connection through approval, execution, and the final business state. Otherwise, the trace can end at “draft created” while the actual task remains unresolved.
Use a stable task identifier across retries and a separate run identifier for each attempt. Keep parent relationships for delegated work and tool calls. A retry should remain visible as another attempt; it should not erase the first failure or appear to be a second completed business task.
The following worksheet is a proposed design for a hypothetical invoice assistant. It reads an invoice, checks the purchase order, and creates a draft for a person to approve. These are suggested application fields, not a telemetry standard or a Hapy deployment.
| Stage | Record by default | Question the operator can answer |
|---|---|---|
| Task entry | Task and run IDs, task type, permitted user or tenant scope, start time | Which task and access scope does this run belong to? |
| Agent configuration | Model identifier, prompt version, tool-policy version, deployment version | What changed between a useful run and a failing run? |
| Retrieval | Source reference and version, result status, duration | Was the purchase order available and current? |
| Tool operation | Tool name, permitted target reference, attempt number, status, duration | Which integration failed, and did it retry? |
| Approval | Proposal reference, approval state, expiry, reviewer reference | Is the draft waiting, denied, expired, or approved? |
| Business completion | Draft or transaction reference, verified state, reconciliation time | Was the task completed, or only proposed? |
| Resource use | Reported token usage, tool usage, estimated cost and pricing version | What did the entire attempt consume? |
References should identify records without copying their sensitive contents into every event. Keep a link to a restricted source record when an authorized investigator needs detail. Record unknown or unavailable fields explicitly. An absent approval event cannot be treated as approval, and an absent completion event cannot be treated as success.
Which metrics need a response?
Measure task outcomes, operational health, and control failures separately. They answer different questions. A system can be available and fast while generating unusable drafts; a careful escalation can be a correct outcome even when the task is not automated to completion. Langfuse’s documentation distinguishes traces, usage and cost, quality scores, dashboards, and alerts as complementary capabilities.
Define the denominator before using a rate
Count unique business tasks when reporting task completion. Report attempts and tool calls separately. For the invoice assistant, distinguish completed drafts, tasks awaiting review, deliberate escalations, failed tasks, and unknown outcomes. State the reporting window and how you handle tasks that began in one window and completed in another.
Estimate cost across all attempts associated with a task. Label it as estimated when the record excludes provider discounts, hosting, review time, or other operating costs. Use the AI automation ROI guide when deciding whether the workflow produces business value; token cost alone cannot answer that question.
Attach each alert to an owner and an action
Choose thresholds from the workflow’s consequence, baseline, and operating limits. Do not copy a universal latency or error-rate threshold from another team’s system. Use an initial policy like this, then test whether it detects the failures that matter:
| Signal | Example response | Owner |
|---|---|---|
| A write occurred without a valid approval | Pause the affected write path and preserve the action record | Security or workflow owner |
| A tool times out and the completion state is unknown | Reconcile the target system before retrying a possible write | Integration owner |
| Repeated calls approach the run budget | Stop the run at its configured limit and route the task for review | Agent operator |
| Pending approvals exceed the workflow’s deadline | Escalate to the backup reviewer; leave the action pending | Business workflow owner |
| Reviewed task quality declines after a version change | Compare affected traces and rerun relevant evaluation cases | Engineering and workflow owners |
A policy denial may show that a control worked. It still needs investigation when denials repeat or reveal an unexpected input. An alert does not grant permission to retry, change a record, or lower an approval requirement. The agent security guide explains the controls that must enforce those boundaries.
How much sensitive content should the system retain?
Collect the minimum content needed to answer a defined operational question. Start with metadata and restricted record references. Enable prompt or response capture only for a justified scope with clear access, retention, and deletion rules. OpenTelemetry’s sensitive-data guidance discusses filtering, transformation, and redaction; apply these controls before telemetry reaches a destination that should not receive the original data.
Test the export path with synthetic sensitive values. Check nested tool arguments, exception messages, URLs, attachments, and evaluation inputs as well as the main prompt. A field-level rule that removes a customer email from one event does not establish that the same email is absent from an error payload.
Sampling can reduce telemetry volume, but it also changes what the team can investigate. Document which routine runs are sampled, which failure or high-impact events must be retained, and what happens when telemetry export fails. Keep required authorization and transaction audit evidence under its own policy. Do not assume a sampled debugging trace satisfies that requirement.
What does an incident review look like?
Suppose the hypothetical invoice assistant reports a timeout while creating a draft. The tool request may have failed before writing, or the draft may exist even though the response never reached the agent. The next action is to reconcile the business record, not immediately repeat the request.
- Find the task ID and its run and tool-attempt records. Confirm the configuration and target scope.
- Check the accounting system for the proposed draft using its correlation or idempotency reference. If the state cannot be verified, keep the outcome unknown and escalate.
- Preserve the relevant events under restricted access. Pause the affected action if the team cannot prevent duplicate writes.
- Separate the cause from the visible symptom: integration outage, missing trace propagation, unsafe retry, stale data, or a poor model decision.
- Turn the failure into a redacted regression case. Use the agent evaluation workflow to test the repair before restoring or expanding the action.
This is a proposed response sequence, not a measured incident result. Its value is the decision it makes possible: distinguish an unexecuted proposal from an uncertain write before another attempt can create a duplicate.
Begin with one real task and ask an operator to reconstruct an allowed run, a timeout, and an expired approval from the evidence. Record the missing fields and response decisions before adding more dashboards. If that exercise exposes gaps between the agent, integrations, and business workflow, Hapy’s business systems automation service can help design the connection. Hapy offers this service and has a commercial interest in that next step.